

The Reality of Network Overhead
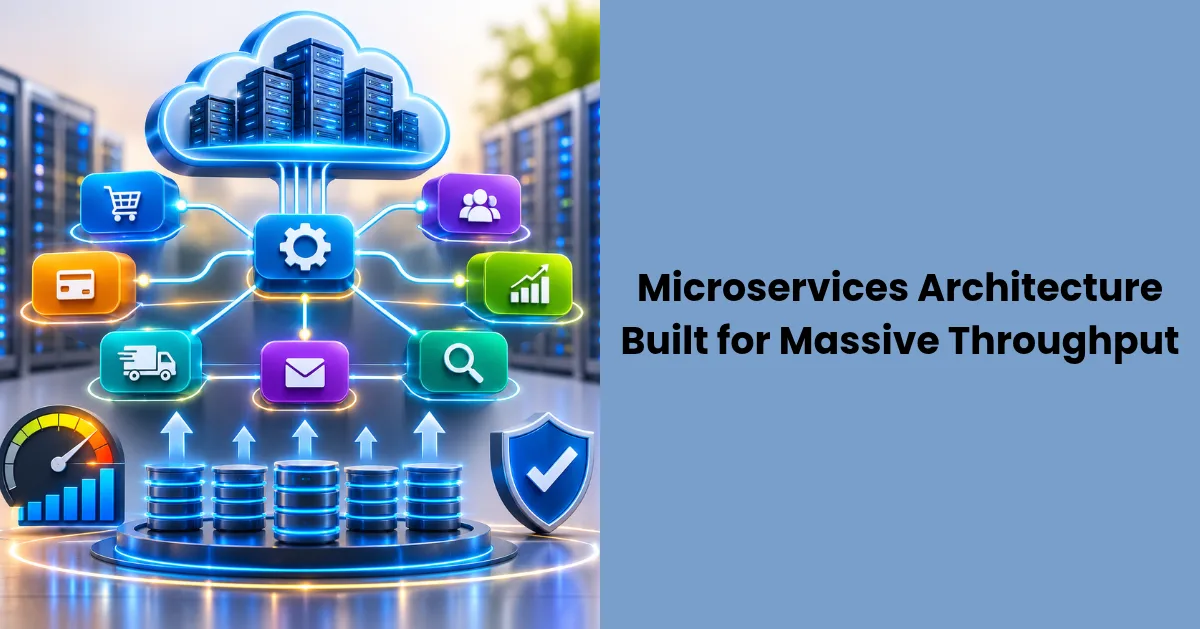
A local function call may take nanoseconds or microseconds, while a remote call must cross a network, pass through protocol layers and wait for another process. A single customer request that triggers 10 sequential service calls can therefore accumulate substantial latency. The performance overhead of micro-services becomes especially noticeable when those network hops multiply across high request volumes.
Measure complete request paths under realistic load, including serialization, encryption and retries. Use parallel calls when dependencies allow it, batch small operations and set strict timeouts. Compact payloads also reduce processing and transfer costs. If two services communicate constantly and always change together, combining them may produce a cleaner and faster boundary.
Selecting High-Concurrency Languages
Language choice affects memory use, scheduling behavior and the ease of diagnosing production issues. Go is a common option for network services because goroutines provide lightweight concurrency, while its standard library includes mature support for HTTP, profiling and cancellation. Java, Rust and other languages can also deliver high throughput when they match the team’s skills and workload.
Run representative benchmarks before committing. Test connection-heavy traffic, CPU-intensive work and sudden bursts instead of relying on simple request-per-second comparisons. Companies building a Go-based platform can hire Golang developers when they need additional experience with concurrency, distributed systems and production profiling.
Hiring decisions should still account for familiarity with the organization’s deployment environment and the specific workloads the service needs to handle.
Managing Distributed State
State becomes harder to reason about once several services participate in one business operation. A checkout flow might reserve inventory, calculate shipping and create a payment record across separate data stores. A failure halfway through that sequence can leave records out of sync if the design assumes one global transaction.
Prefer clear ownership, with one service responsible for writing each data domain. Use idempotency keys so repeated requests don’t create duplicate orders and adopt an outbox pattern when database changes must reliably produce events. For longer workflows, compensating actions can release a reservation after a later step fails.
The same principles matter when designing a scalable ecommerce architecture, where data flow, integrations and platform constraints can all affect performance. Document expected consistency delays so product teams know when users may briefly see stale information.
Monitoring Telemetry in Real Time
Massive throughput requires telemetry that connects symptoms to specific requests. Collect metrics for request rate, error rate and latency at every service boundary. Distributed traces should carry one correlation identifier across queues and synchronous calls, while structured logs should include service version, region and operation name.
Focus alerts on user-visible failure and exhausted capacity. For example, alert when the 99th-percentile checkout latency exceeds its service objective for a sustained period, not whenever one server records a brief CPU spike. Dashboards should expose queue depth, retry volume, database saturation and dependency latency alongside application metrics.
Control telemetry costs as traffic grows. Sample successful traces at a lower rate, preserve failed or unusually slow traces and limit high-cardinality labels such as customer IDs. This approach keeps real-time investigation practical without turning the monitoring pipeline into another bottleneck.
Throughput testing should end with a failure exercise, not a peak request count. Disable one dependency during a load test and confirm that timeouts, retries and recovery stay within the latency budget. That result reveals far more about production readiness than an ideal-condition benchmark.


