

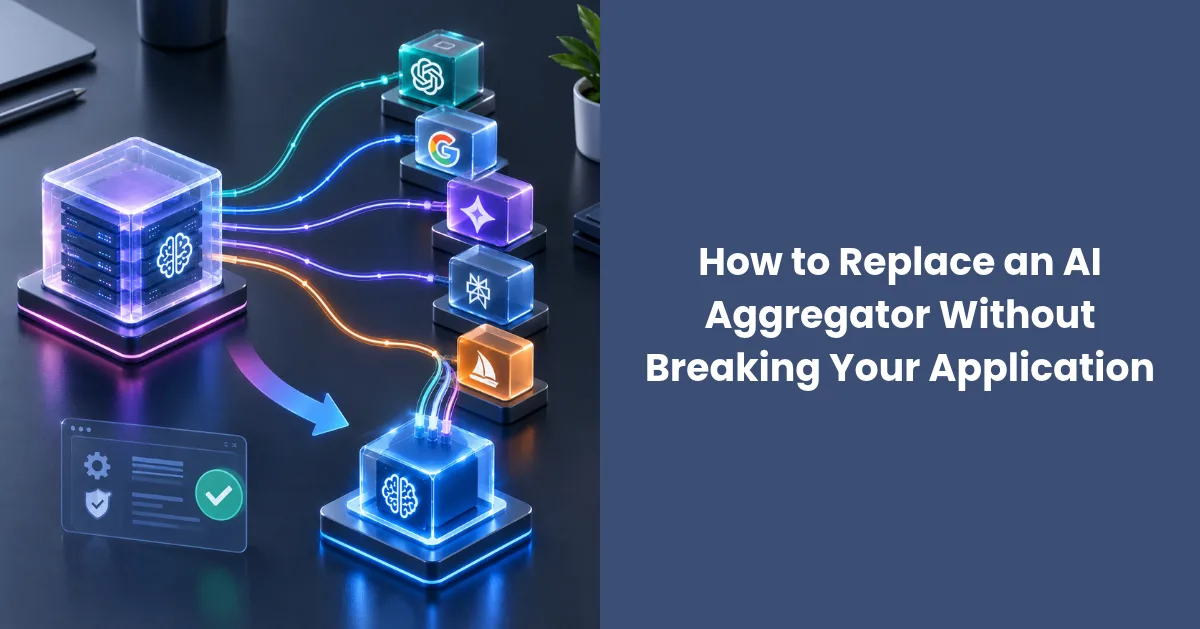
The difficulty appears when the application outgrows the original arrangement. Perhaps the next release needs a media model that is not available through the current account. Perhaps the team needs to separate production spend from experiments. Or perhaps document processing and generative features now require different infrastructure. Replacing the aggregator is no longer a matter of changing an API key. It is a controlled migration of application behavior.
A good migration preserves what already works while making the new requirements explicit. The objective is not to find a service that appears identical on a comparison page. It is to understand which responsibilities should remain centralized, which belong with a specialist provider, and which should move into the application itself.
Start with the Workload, Not the Vendor Category
The phrase “AI aggregator” covers services that solve different problems. One may provide hosted access to language models. Another may combine document extraction, translation, speech, and image services. A gateway may concentrate on routing and observability while expecting the customer to supply provider credentials. A deployment platform may let the team operate its own model endpoint.
These services overlap, but they are not interchangeable. An application that extracts fields from invoices has different requirements from one that generates product images. A coding assistant needs a reliable tool loop and predictable context handling. A transcription workflow depends on audio limits, language coverage, and the distinction between batch and streaming processing.
Write down the actual jobs before comparing platforms. Identify the input, expected output, maximum acceptable wait, data sensitivity, and downstream action for each workflow. This makes it harder for an impressive model catalog to distract the team from a missing capability that would block deployment.
Separate generative tasks from traditional AI services in this inventory. Moving a chat feature to a multi-model API does not automatically replace an existing OCR or document-processing integration. Keeping a specialist service for one workload can be the cleaner design, even when it means retaining more than one supplier.
Make the Existing Contract Visible
An integration contract is larger than its endpoint path. It includes authentication headers, supported request fields, response structure, timeout behavior, streaming events, usage reporting, and the meaning of an error. Some of these details may have become assumptions scattered across the codebase.
Put a thin application-owned adapter around the current provider before introducing another one. The adapter should accept the business request and return a stable result that the rest of the application understands. Provider-specific model identifiers and optional parameters belong behind that boundary rather than inside user-facing features.
For a text feature, the normalized result might include generated content, a completion status, and reported usage when available. For a media feature, it may need a job identifier, a pending state, an output location, and an expiry policy. For document extraction, it may need a structured object and a clear representation of missing fields.
Avoid normalizing away differences that the application must handle. A response marked incomplete should not look identical to a completed answer. A provider that cannot support a required output schema should not silently fall back to unconstrained prose. The contract should simplify integration without hiding relevant limitations.
Choose Where Abstraction Actually Helps
A shared access layer is useful when several workflows benefit from consistent account management and a common request interface. It can reduce repetitive integration work and make it easier to compare models without rebuilding the surrounding application.
It is less useful when the abstraction removes a feature the product needs. A specialized image-editing control, document-processing setting, or provider-specific tool may justify a direct integration. Preserving those capabilities can be more valuable than presenting every request through an identical interface.
The available paths become clearer when comparing Eden AI alternatives by workload rather than assuming that every platform in the category replaces the same services. The practical choice is between responsibilities: hosted model access, broader AI-service aggregation, gateway control, and custom deployment.
A hybrid architecture is often a reasonable outcome. The application can use a common adapter for ordinary text generation, a specialist endpoint for media processing, and a dedicated service for document extraction. The important requirement is a deliberate boundary, not a single vendor name on the architecture diagram.
Build a Test Set That Reflects Production
A migration test should use representative business requests rather than a collection of impressive demos. Include routine inputs, ambiguous inputs, malformed requests, and examples that previously caused support tickets. Keep expected behavior close to the product's actual acceptance criteria.
For generated text, assess whether the answer completes the task, follows the requested structure, and avoids introducing unsupported details. For extracted data, compare field values and missing-field behavior. For images, assess the requested edit, preservation of important visual details, and whether the output is usable in the intended workflow.
Test more than the model response. Verify the application's handling of rate limits, empty outputs, unsupported parameters, network interruptions, and delayed jobs. A technically valid response can still be unusable if the surrounding workflow cannot interpret it correctly.
Record failures by category. If an output fails because the prompt assumes a feature unavailable on the new model, the remedy may be a prompt or product change. If the request never reaches the provider because the adapter serializes a field incorrectly, that is an integration defect. Treating both as “model quality” makes troubleshooting harder.
Treat Retries and Fallbacks as Product Behavior
Retries are easy to add and expensive to misunderstand. A connection timeout does not necessarily mean that the original request was never processed. Retrying a generation job can create duplicate outputs or additional charges unless the endpoint provides a documented way to avoid that outcome.
Define which failures are safe to retry and which require a status check or a user-visible error. Keep retry limits and waiting behavior explicit. A background task can tolerate a different recovery strategy from an interactive assistant where the user is waiting for an answer.
Fallbacks also need a business contract. Switching providers is not enough if the replacement model produces a different output type, cannot use the required tool, or handles an uploaded asset differently. Maintain a compatibility map for each fallback path instead of assuming that any available model is an acceptable substitute.
For sensitive workflows, a failure may be preferable to an unapproved substitution. The application should not send confidential inputs to another service merely because the primary route is unavailable. Routing policy and data policy need to agree before automatic recovery is enabled.
Compare the Cost of Completed Work
Published rates are useful inputs, but a migration decision should consider the cost of a successful business task. A cheaper request may require more attempts, longer prompts, manual corrections, or a separate processing step. Those differences can outweigh a lower headline rate.
For an image workflow, define the output settings before comparing invoices. Resolution, number of outputs, editing mode, and retries all matter. For video, duration and generation settings change the unit being purchased. For text, input length, generated output, and repeated tool calls affect the bill.
Keep provider usage records separate from the application's own counters. The application should know which job generated which requests, while the provider remains the authority for billed usage. Reconcile the two during a pilot rather than waiting until a large production invoice exposes a mismatch.
Do not confuse prepaid access, a free trial, and a recurring free allowance. They have different implications for budgeting and product onboarding. Confirm the current terms of the selected service without building a production plan around a temporary offer.
Roll Out in a Way You Can Reverse
Begin with a workflow that has clear acceptance criteria and limited operational risk. Keep the existing route available while a small portion of eligible traffic uses the replacement. Compare results using the same measurements that defined the test set.
A useful rollout has a clear stop condition. Rising error rates, unexpected spending, unacceptable output quality, or a missing feature should trigger investigation before more traffic moves. The decision should not depend on whether the team has already invested considerable time in the migration.
Preserve enough configuration history to return to the previous route. That includes model identifiers, prompt versions, adapter settings, timeout values, and any feature flags controlling provider selection. Reversibility is an architectural property, not simply an instruction to change an environment variable later.
Once the replacement has proved itself, remove obsolete integration paths deliberately. Rotate unused credentials, update support documentation, and confirm that monitoring follows the new route. Leaving abandoned keys and adapters in place makes the next migration harder to understand.
Keep the Boundary You Own
The lasting benefit of a well-run migration is not the new account. It is a clearer separation between the application's business logic and the services that execute AI requests. That separation gives the team room to adopt better models, retain specialist capabilities, and change suppliers without rewriting the product each time.
Choose the platform that serves the workload, but keep responsibility for the user experience inside the application. A unified API can simplify access. It cannot decide what counts as an acceptable answer, a successful edit, or a safe recovery path for the product you are building.